Hello, I'm Hideyuki Ichiwara from the Robotics Team. Our team is currently developing Vision-Language-Action (VLA) models with the goal of realizing general-purpose foundation models for robots. In this article, I would like to introduce the data collection approach we are actively working on.
What is UMI?
Universal Manipulation Interface (UMI)*1 is a low-cost, universal data collection device and learning framework proposed by Stanford University and the Toyota Research Institute (TRI). By using a handheld device equipped with a camera that mimics a robot's gripper, humans can collect data simply by demonstrating tasks across various environments. This approach leverages a robot-agnostic representation based on the end-effector pose, enabling the acquisition of generalized policies independent of the specific robot model, provided the gripper and camera conditions are consistent.
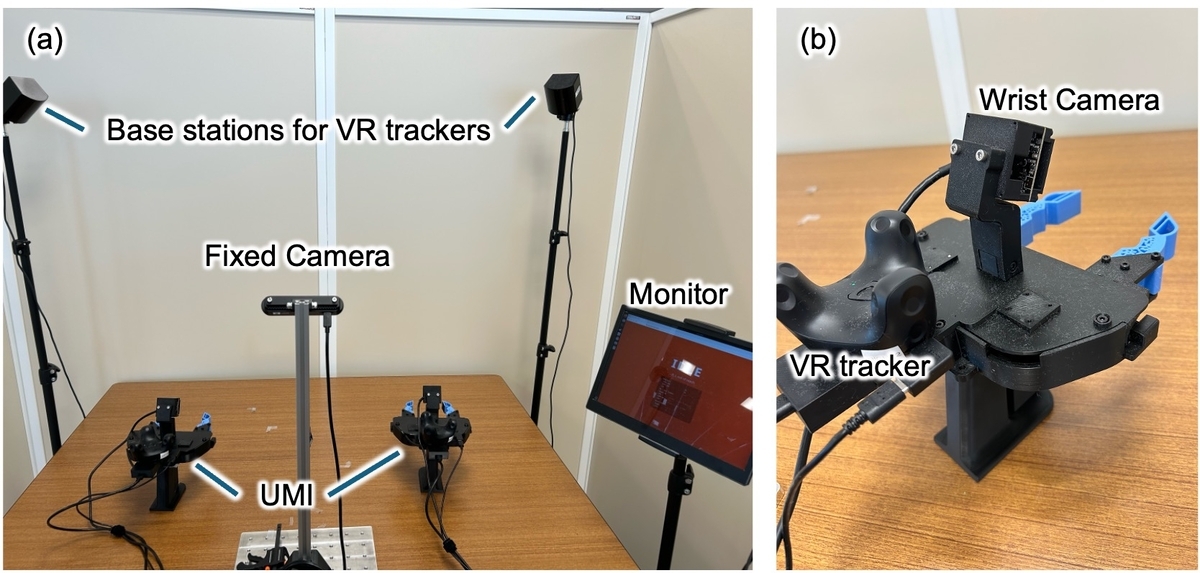
In the original research, the trajectory of the end-effector's pose was estimated based on images from an action camera and IMU data. However, the estimation performance heavily depended on background conditions (such as the richness of visual features) and how the hand was moved, which led to challenges in data efficiency. To address this, our team is exploring an approach that measures the end-effector pose using alternative tracking methods such as VR trackers (Fig. 1), established in several prior works*2, *3. However, the key point of this report is not just the use of VR trackers. While building this high-precision data collection system, we discovered a significant gap between the hardware and the system when deploying the learned policy onto our physical custom robot. Therefore, the core focus of this article is to introduce three unglamorous yet essential engineering efforts across Measurement, Control, and Computer Vision that were required to successfully make this VR tracker-based UMI system work on a real-world custom robot.
Challenges
While VR trackers provided a robust solution for collecting trajectory data in the real world, deploying that learned policy onto a physical robot introduced a completely different hardware challenge: precise joint calibration. In UMI research, the robot's end-effector is controlled based on data collected via human demonstrations using a handheld device. For the robot arm to accurately drive its end-effector to the target position in space, its joints must be precisely calibrated (zero-point adjustment).
This might sound like an obvious requirement. However, in scenarios where data is collected via standard teleoperation and the policy is deployed on the exact same robot, this zero-point deviation is rarely an issue. Since the exact same zero-point deviation is present during both data collection and deployment, the errors effectively cancel each other out. In many UMI-related studies, high-precision robots like the UR series or Franka Emika Panda are typically used, so this issue was rarely discussed explicitly.
Our team is developing with a customized robot based on the "Openarm"*4 developed by Enactic, which is driven by QDD (Quasi-Direct Drive) motors. For such custom-built robots, calibration is typically performed using mechanical end stops or by defining a reference posture. However, due to assembly tolerances and minor part discrepancies, a gap emerged between the actual joint ranges and their design values. This resulted in an end-effector positioning error of several centimeters.
To successfully deploy UMI on this hardware, we had to address three fundamental engineering pillars
- Measurement: Eliminating the joint zero-point offset errors caused by assembly tolerances.
- Control: Achieving physical compliance through gravity compensation, which is necessary for high-precision manual calibration (teaching).
- Computer Vision: Correcting the shift in intrinsic camera parameters that occurred when we changed the lens to achieve a wider Field of View (FoV).
In the following sections, we will detail these three essential engineering approaches.
Approach: 3 Essential Engineering Pillars
1. Joint Kinematics Calibration (Measurement)
For the robot arm to accurately drive its end-effector to the target position, its joints must be precisely zero-point calibrated. To resolve this, we decided to implement a calibration method based on the XYZ 4-point method*5, *6, a technique widely used in industrial robotics. This is a geometric method where the robot approaches a fixed reference point in space (usually a sharp pin tip) from at least four different postures. By ensuring the unknown TCP (Tool Center Point) consistently matches this fixed point, we can back-calculate the TCP position vector and joint offsets from the robot's joint angles. Building upon this geometric constraint, we formulated the calibration as an optimization problem.
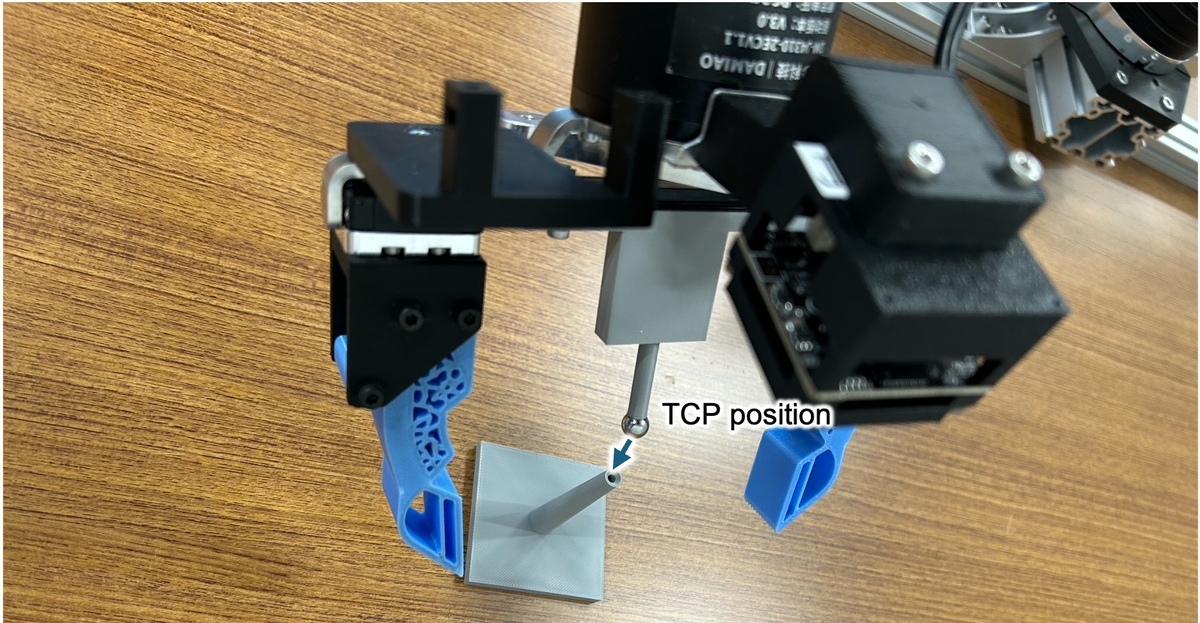
The core of this method relies on a geometric constraint: "The end-effector is aligned with the exact same physical point in space from different joint angles (postures)."
Let be the number of acquired postures,
be the measured joint angles at the
-th posture (for a 7-DoF arm,
), and
be the "true offset correction value" we want to find. If we define the robot's forward kinematics as a function
, the calculated TCP coordinate
at each posture can be expressed as:
In the real world, the robot is touching the exact same physical point. Therefore, if is perfect, the calculated
should perfectly coincide across all postures
. However, because the initial state contains offset errors, there will be variance in this set of points. We define the centroid (average coordinate)
of these points as:
The goal of the optimization is to find a that minimizes the distance (variance) between each TCP coordinate
and the centroid
. Specifically, we formulate this as an optimization problem minimizing the following objective function
:
The first term minimizes the variance of the end-effector positions. The second term is a regularization penalty, where is the "maximum physically possible error" derived from the encoder and mechanical design values. To prevent the optimization algorithm (we used Differential Evolution) from outputting unrealistically large correction values, we apply a constraint by multiplying a tiny weight
(e.g.,
).
Furthermore, because the XYZ 4-point method requires a human operator to manually guide and align the robot to a specific point, slight hand tremors or limitations in visual alignment inherently introduce some measurement variance
2. Gravity Compensation and Compliance (Control)
Because our robot utilizes QDD motors, we can take advantage of highly transparent torque control. However, to truly unlock this hardware capability, implementing an accurate gravity compensation controller is absolutely vital.
To understand why this is essential from a control perspective, let's look at the standard rigid-body dynamics combined with a PD (Proportional-Derivative) control law that includes a feedforward gravity term*8:
Here, is the inertia matrix,
is the Coriolis/centrifugal term, and
is gravity.
is the external torque applied to the robot (e.g., human pushing). In the control law,
and
are the desired and current joint angles, and
are the control gains.
By substituting the commanded torque () into the dynamics equation, the gravity term
perfectly cancels out. If we assume a quasi-static state where the arm is moved slowly by hand (velocity
, acceleration
), the equation simplifies to:
If we did not accurately compute and inject the term, the PD controller alone would have to fight gravity. To prevent the arm from sagging (steady-state error), we would be forced to set the proportional gain
extremely high. A high
makes the robotic arm inherently stiff and rigid.
By explicitly canceling gravity, the PD controller only needs to handle trajectory tracking errors. This allows us to use significantly lower control gains ( and
). It is this low-gain control, combined with the inherently low mechanical friction of QDD motors, that grants the arm true physical compliance.
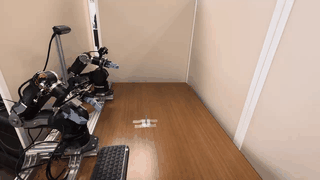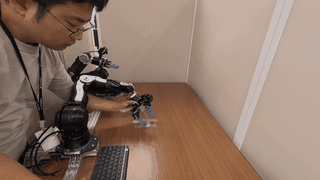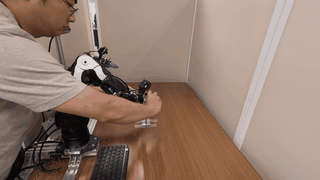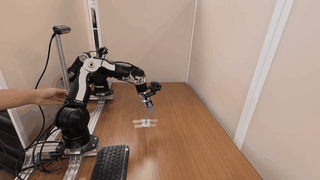
This compliance is extremely beneficial for manual operations. For example, during the XYZ 4-point calibration mentioned earlier, we continuously update the target joint angles to match the current ones (). This zeroes out the algorithmic restoring force (
), allowing us to seamlessly and precisely guide the TCP by hand without fighting the motors.
3. Camera Intrinsic Calibration (Computer Vision)
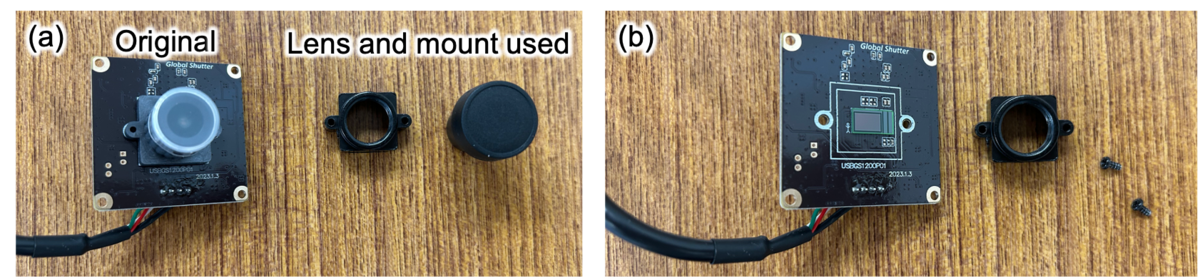
Finally, to match the visual domain, we had to address the camera hardware. In our setup, we replaced the standard USB camera lens to achieve a wider field of view. While this sounds like a simple hardware modification, changing a lens and lens mount almost always causes the image center (principal point) to shift significantly, alongside introducing new lens distortion. As shown in Fig. 4 (b), the lens mount is secured with screws, meaning that slight misalignments can easily occur during assembly, leading to individual discrepancies between each camera unit. Performing a rigorous intrinsic camera calibration—for which we utilized the OpenCV library—is a basic but essential procedure in computer vision. Skipping it means the spatial mapping between the camera's visual observations and the physical action space will be misaligned, leading to a critical discrepancy between the human-demonstrated data and the robot's execution. We also used the 4-point method to estimate the relative pose between the handheld device's TCP and the VR tracker to ensure total spatial consistency.
Results
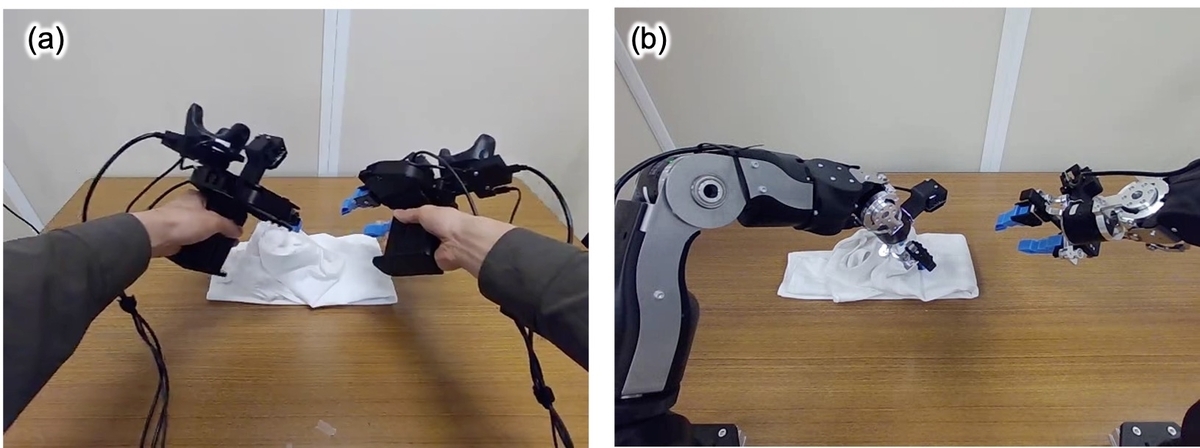
To evaluate task performance, we tested the imitation learning policy on a simple pick-and-place task (which requires sub-centimeter precision) and a T-shirt folding task (to test applicability to complex tasks). As a result, we confirmed spatial generalization in the pick-and-place task and the successful execution of the folding task.
Interestingly, we also used images from a top-down camera as input in this experiment. During data collection, the human operator's hands are visible in the frame, meaning the visual domain differs significantly from when the policy is deployed on the robot. We were initially concerned about how this would affect performance*9. However, remarkably, the robot was able to execute the tasks without requiring any special masking techniques (Fig. 5).
Conclusion
In this article, I introduced our UMI-based data collection approach, with a particular focus on the critical calibration and control processes required for our customized robot.
Recently, we have seen many highly impactful demonstration videos in the context of Physical AI. However, I want to emphasize that behind these flashy demos lies a foundation of gritty, unglamorous engineering efforts like the ones described here. Additionally, it is important to note that the setup and methodologies described in this article are intended strictly for research and development prototypes.
With UMI-based approaches, errors accumulate from various factors — from tracking discrepancies to mechanical tolerances. Tasks that demand sub-millimeter precision are difficult to achieve through naive engineering alone. Moving forward, we plan to explore policy refinement methods directly on real robots to overcome these remaining challenges.
*1:Chi, Cheng, et al. "Universal Manipulation Interface: In-The-Wild Robot Teaching Without In-The-Wild Robots." Robotics: Science and Systems XX (2024).
*2:AGILE-X, pika, https://global.agilex.ai/products/pika
*3:Liu, Songming, et al. "RDT2: Exploring the Scaling Limit of UMI Data Towards Zero-Shot Cross-Embodiment Generalization." arXiv preprint arXiv:2602.03310 (2026).
*4:Enactic, Openarm, https://openarm.dev/
*5:Geiger, Davi. “Autonomous Robot Calibration for Hand-Eye Coordination.” The International Journal of Robotics Research, SAGE Publications, 1991.
*6:Shawn Dietrich, "Methods of Performing Robot Tool Center Point Calibration." Control.com, https://control.com/technical-articles/methods-of-performing-robot-tool-center-point-calibration/
*7:Cakir, Mustafa, and Cengiz Deniz. "High precise and zero-cost solution for fully automatic industrial robot TCP calibration." Industrial Robot: the international journal of robotics research and application 46.5 (2019): 650-659.
*8:Practical Robot Control: From Fundamentals to Dynamics (実践 ロボット制御: 基礎から動力学まで), ISBN: 978-4-274-22430-0
*9:Rayyan, Omar, et al. "Mv-umi: A scalable multi-view interface for cross-embodiment learning." IEEE Access (2026).
