(Japanese version follows English one/英語版の後に日本語版が続きます。)
Contributor
Shiqi Yang
Creative Vision Team, Multimodal AI Department
Motivation
World Action Models (WAMs) have recently emerged as a promising direction for embodied intelligence [1, 2, 3]. They connect visual world models with robot action generation, offering a path toward policies that learn not only what action to take, but also how the visual world changes around that action. Building on our experience with video generation and world model, WAMs are a natural next direction for our team.
Few-step distillation has already become a practical part of our work on interactive talking-character systems and video world models. In both settings, iterative generation can produce strong outputs while remaining too slow for an interactive product: each denoising step adds another model forward pass to the critical path.
Many WAMs face the same deployment bottleneck because they rely on iterative generation through diffusion or flow-matching objectives. Fast-WAM [4] removes future-video imagination from test time, while Flash-WAM [5] distills joint video-action generation into fewer steps.
Our experiment sits at the intersection of these ideas. Starting from the released Fast-WAM checkpoint, we adapt Flash-WAM’s action-side consistency-distillation idea to Fast-WAM’s native inference graph and train exclusively on offline LIBERO data. We ask two focused questions: how much of the original 10-step policy’s benchmark success rate survives naive one- or two-step inference, and how much of the remaining gap does consistency distillation close?
Fast-WAM: Learning with Video, Acting without Future Imagination
Fast-WAM retains video-action co-training while skipping future-video generation at test time [4]. The released model in this repository uses a Mixture-of-Transformers architecture with two experts:
- a roughly 5B-parameter Wan2.2-TI2V video expert from the Wan model family [6];
- a roughly 1B-parameter ActionDiT expert for robot actions.
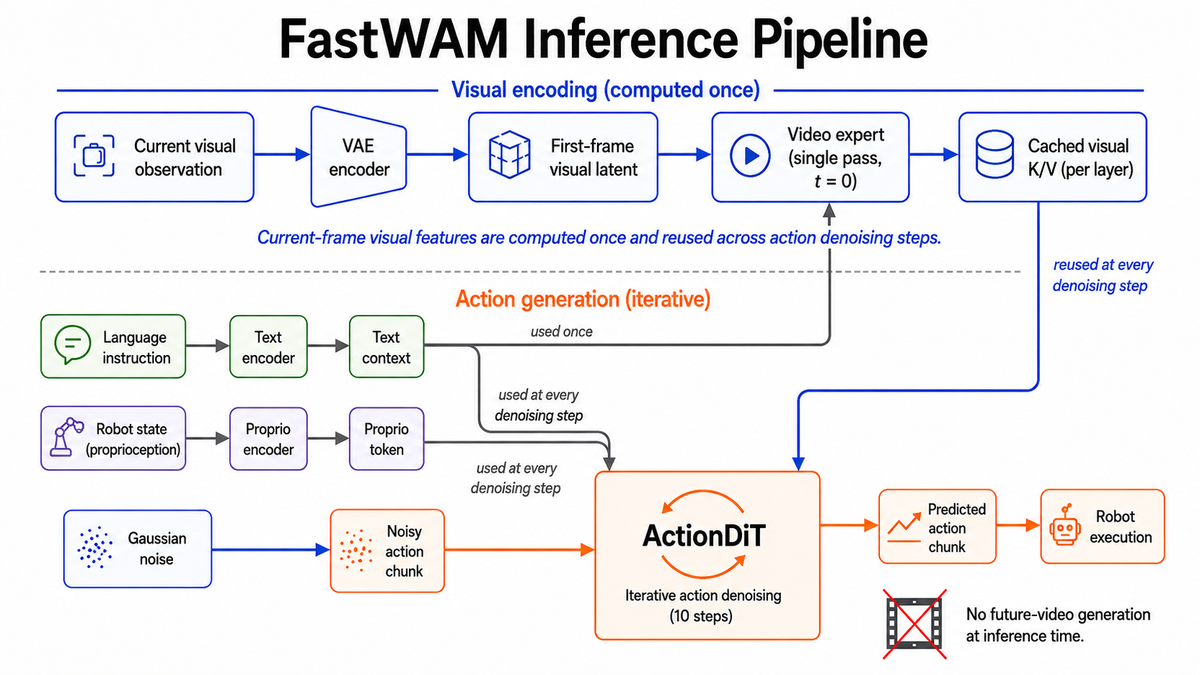
During action inference, the VAE encodes the current clean observation. The video expert processes the first-frame representation once at timestep zero and stores per-layer key-value features. The action expert then denoises an action chunk while attending to those cached visual features, the language instruction, and proprioception.
The key architectural detail is that the action branch does not attend to a denoised future-video latent. Fast-WAM’s released configuration performs 10 action-denoising steps using the current clean observation, so a method designed for joint video-action denoising cannot be copied operator for operator.
FlashWAM: Modality-Aware Consistency Distillation
FlashWAM applies consistency distillation to the joint video-action model LingBot-VA [5, 7], using separate consistency parameterizations for the video and action noise regimes. A frozen teacher advances the noisy sample, an online student learns from an exponential-moving-average (EMA) target at the trajectory endpoint, and an action-aware flow-matching term regularizes action prediction [5].
Our Adaptation: Distilling Only the Fast-WAM Action Expert
Our implementation keeps Fast-WAM’s deployment graph intact. Rather than adding a generated-future-video dependency, we apply the consistency objective only where Fast-WAM still performs iterative generation: the ActionDiT expert.
The resulting training setup contains three action experts:
- Frozen teacher: the ActionDiT expert from the released Fast-WAM checkpoint;
- Online student: a trainable copy initialized from the teacher;
- EMA target: a frozen moving average of the online student.
The VAE, video expert, and proprio encoder remain frozen. For each sample, the clean first frame is encoded and passed through the video expert once to construct the same key-value cache used by native Fast-WAM inference. That cache is shared by the teacher, online student, and EMA target, so all three action predictions receive identical visual, language, and proprioceptive conditioning.
Consistency objective
We apply consistency distillation [5, 7] specifically to the action stream. The frozen teacher advances the noisy action along its denoising trajectory, while the online student learns to match the EMA target evaluated at the resulting lower-noise point.
For a normalized ground-truth action chunk , Gaussian noise
, and a sampled noise level
, we construct
The teacher then predicts a flow velocity and takes one Euler step to
:
The action stream uses the -style consistency output
The online output at matches the EMA target at
under a Huber loss. Following FlashWAM [5], an action-aware term also keeps the online velocity close to the flow-matching target
:
This is an action-side adaptation rather than a model-level reproduction of FlashWAM: we do not jointly distill video, and we retain Fast-WAM’s native shifted action scheduler.
Offline Training on LIBERO
We train exclusively on the four preprocessed LIBERO subsets, LIBERO-10, LIBERO-Goal, LIBERO-Spatial, and LIBERO-Object [8], containing 277,713 frames and 40 unique language instructions. Each example provides two camera views, an action chunk, proprioception, and a precomputed text embedding. Sampling follows the natural frame distribution of the merged datasets.
The training stride targets a two-step trajectory. We report full closed-loop evaluation at one and two action steps, with the original 10-step Fast-WAM policy as the teacher reference.
Controlled LIBERO Results
We first isolate the comparison that this experiment can support. Every row below uses the same Fast-WAM architecture, released initialization, offline LIBERO training distribution, and local evaluation recipe. For each setting, we run 10 tasks per LIBERO suite and 50 trials per task: 2,000 closed-loop episodes in total. Like the released Fast-WAM model [4], none of these variants uses embodied pretraining.
| Variant | Action steps | Distilled? | Success rate | Successful episodes | Action NFE reduction | |
|---|---|---|---|---|---|---|
| Fast-WAM reference | 10 | No | 97.60% | 1,952/2,000 | — | — |
| Fast-WAM, naive step reduction | 2 | No | 96.50% | 1,930/2,000 | -1.10 pp | 5× fewer |
| Distilled Fast-WAM (ours) | 2 | Yes | 96.80% | 1,936/2,000 | -0.80 pp | 5× fewer |
| Fast-WAM, naive step reduction | 1 | No | 96.20% | 1,924/2,000 | -1.40 pp | 10× fewer |
| Distilled Fast-WAM (ours) | 1 | Yes | 96.55% | 1,931/2,000 | -1.05 pp | 10× fewer |
The suite-level breakdown shows where those totals come from. Long denotes LIBERO-10, following the source benchmark.
| Variant | Steps | Spatial | Object | Goal | Long | Average |
|---|---|---|---|---|---|---|
| Fast-WAM reference | 10 | 98.2 | 100.0 | 97.0 | 95.2 | 97.6 |
| Fast-WAM, naive step reduction | 2 | 97.6 | 99.2 | 95.8 | 93.4 | 96.5 |
| Distilled Fast-WAM (ours) | 2 | 96.8 | 99.6 | 96.6 | 94.2 | 96.8 |
| Fast-WAM, naive step reduction | 1 | 98.0 | 99.4 | 95.6 | 91.8 | 96.2 |
| Distilled Fast-WAM (ours) | 1 | 97.0 | 98.8 | 97.0 | 93.4 | 96.55 |
The strongest finding is not that distillation makes few-step Fast-WAM possible. The released model is already highly few-step friendly: naive two-step and one-step inference retain 96.5% and 96.2% success, respectively. Distillation slightly closes the remaining benchmark gap, adding 6 successful episodes at two steps (+0.30 pp) and 7 at one step (+0.35 pp). Without repeated evaluation seeds, we do not interpret these small differences as statistically significant improvements.
Instead, the experiment establishes that Flash-WAM’s consistency objective can be transferred to Fast-WAM’s action stream without changing its native deployment graph. It also suggests that the value of step distillation depends on the WAM architecture: in Fast-WAM, clean-observation conditioning and a decoupled action trajectory may already make aggressive step reduction comparatively robust. This is a plausible architectural explanation, not a causal claim established by the present benchmark.
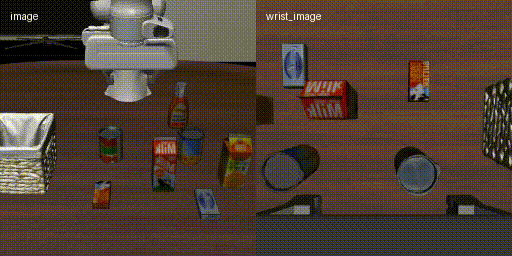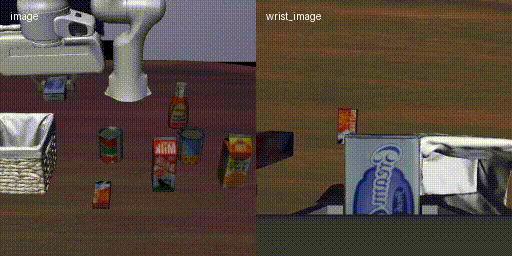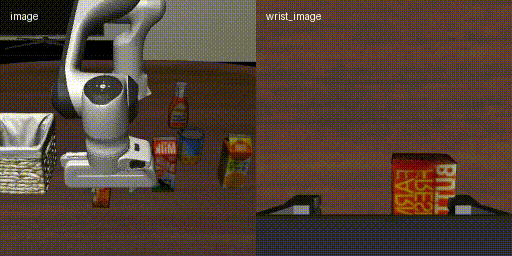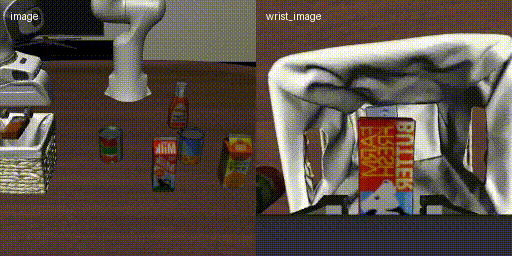
The 5×/10× figures refer only to reductions in ActionDiT function evaluations and should not be read as end-to-end speedups.
Measured from a preprocessed GPU-resident observation and cached task embedding to a CPU-resident 32-action chunk, the 1-step distilled Fast-WAM reduces policy latency from 243 ms to 52 ms (4.63×) on an NVIDIA H100. This timing includes VAE observation encoding, proprio conditioning, clean-frame video KV prefill, ActionDiT denoising and Euler updates, and output transfer, while excluding text encoding, model loading, simulation, rendering, and video I/O.
Concurrent Work: Faster-WAM
While this post was being prepared, Faster-WAM [12] was submitted on August 3, 2026. It reduces action-inference cost by redesigning the action module itself: a lightweight single-layer action head is docked onto a 30-layer video backbone. The paper reports 66.5 ms end-to-end latency in its controlled comparison, a 3.2× speedup over Fast-WAM [4].
Our study targets a different computational axis: post-training reduction of the action-denoising step count while retaining the released Fast-WAM architecture and starting from its checkpoint. We do not directly compare the two approaches because their architectures and evaluation environments differ, and we have not tested whether the techniques compose.
What This Experiment Shows
Fast-WAM already preserves a high LIBERO success rate under naive one- and two-step inference. Action-side consistency distillation recovers a modest share of the remaining gap and, more importantly, demonstrates that a video-derived consistency objective can be transferred to an action-only inference graph. The precise claim supported here is preservation of benchmark success rate under step compression; we did not evaluate action-trajectory or policy-behavior equivalence.
Published Benchmark Context
The following numbers provide background on the broader field, not a leaderboard-style comparison with our controlled experiment. The methods differ in architecture, embodied pretraining, data, and evaluation recipe, so the table should not be used to attribute gains to distillation or to rank the five local Fast-WAM settings above.
| Method | Embodied pretraining | Spatial | Object | Goal | Long | Average |
|---|---|---|---|---|---|---|
| OpenVLA [9] | ✓ | 84.7 | 88.4 | 79.2 | 53.7 | 76.5 |
| ✓ | 96.8 | 98.8 | 95.8 | 85.2 | 94.1 | |
| ✓ | 98.8 | 98.2 | 98.0 | 92.4 | 96.9 | |
| Motus [2] | ✓ | 96.8 | 99.8 | 96.6 | 97.6 | 97.7 |
| LingBot-VA [1] | ✓ | 98.5 | 99.6 | 97.2 | 98.5 | 98.5 |
| Distilled LingBot-VA (Flash-WAM) [5], 2 steps | ✓ | 97.0 | 92.8 | 96.4 | 98.0 | 95.7 |
| Distilled LingBot-VA (Flash-WAM) [5], 1 step | ✓ | 96.0 | 92.6 | 96.0 | 95.8 | 95.1 |
References
[1] Causal World Modeling for Robot Control. arXiv:2601.21998
[2] Motus: A Unified Latent Action World Model. arXiv:2512.13030
[3] World Action Models are Zero-shot Policies. arXiv:2602.15922
[4] Fast-WAM: Do World Action Models Need Test-time Future Imagination? arXiv:2603.16666
[5] Flash-WAM: Modality-Aware Distillation for World Action Models. arXiv:2606.05254
[6] Wan: Open and Advanced Large-Scale Video Generative Models. arXiv:2503.20314
[7] Consistency Models. arXiv:2303.01469
[8] LIBERO: Benchmarking Knowledge Transfer in Lifelong Robot Learning. arXiv:2306.03310
[9] OpenVLA: An Open-Source Vision-Language-Action Model. arXiv:2406.09246
[10] : A Vision-Language-Action Flow Model for General Robot Control. arXiv:2410.24164
[11] : A Vision-Language-Action Model with Open-World Generalization. arXiv:2504.16054
[12] Faster-WAM: Do World Action Models Need Deep Action Modules? arXiv:2608.02365
Fast-WAMの少ステップ蒸留:World Action Modelの行動生成を高速化する
執筆メンバー
Shiqi Yang
Multimodal AI部門 Creative Visionチーム
動機
World Action Models(WAM)は近年、身体性知能に向けた有望なアプローチとして登場しました [1, 2, 3]。WAMは視覚的な世界モデルとロボットの行動生成を結び付け、どの行動を取るかだけでなく、その行動によって視覚世界がどのように変化するかも学習するポリシーへの道を開きます。動画生成と世界モデリングで培った経験を踏まえると、WAMは私たちのチームにとって自然な次のステップと言えます。
数ステップ蒸留は、インタラクティブな会話キャラクターシステムや動画世界モデルの研究において、すでに実用的な手法となっています。どちらの場合も反復生成は高品質な出力を生みますが、デノイジングのステップごとにモデルの順伝播がクリティカルパスに追加されるため、インタラクティブな製品には遅すぎることがあります。
多くのWAMは、拡散またはフローマッチング目的による反復生成に依存しているため、デプロイ時に同じボトルネックを抱えています。Fast-WAM [4]はテスト時の未来動画の生成を不要にし、Flash-WAM [5]は動画と行動の同時生成をより少ないステップに蒸留します。
本実験は、これら2つのアイデアを組み合わせたものです。公開されたFast-WAMチェックポイントを出発点として、Flash-WAMの行動側一貫性蒸留のアイデアをFast-WAM固有の推論グラフに適用し、オフラインのLIBEROデータのみで学習しました。ここでは、元の10ステップポリシーのベンチマーク成功率が、単純な1ステップまたは2ステップ推論でどの程度維持されるか、そして残る差を一貫性蒸留がどの程度縮めるかという2つの問いに焦点を当てます。
Fast-WAM:動画で学習し、未来を想像せずに行動する
Fast-WAMは動画と行動の共同学習を維持しつつ、テスト時の未来動画生成を省略します [4]。このリポジトリで公開されているモデルは、2つのエキスパートによるMixture-of-Transformersアーキテクチャを使用します。
- Wanモデルファミリー [6]の約50億パラメータのWan2.2-TI2V動画エキスパート。
- ロボット行動用の約10億パラメータのActionDiTエキスパート。
行動推論では、VAEが現在のクリーンな観測をエンコードします。動画エキスパートはタイムステップ0で最初のフレーム表現を一度処理し、層ごとのキー・バリュー(KV)特徴を保存します。その後、行動エキスパートは、キャッシュされた視覚特徴、言語指示、固有受容情報にアテンションしながら、行動チャンクをデノイズします。
重要なアーキテクチャ上の特徴は、行動ブランチがデノイズ済みの未来動画潜在表現にアテンションしないことです。Fast-WAMの公開設定は現在のクリーンな観測を用いて10回の行動デノイジングステップを実行するため、動画と行動の同時デノイジング向けに設計された手法をそのまま適用することはできません。
FlashWAM:モダリティ対応の一貫性蒸留
FlashWAMは、動画・行動統合モデルLingBot-VA [5, 7]に一貫性蒸留を適用し、動画と行動それぞれのノイズ領域に別々の一貫性パラメータ化を用います。凍結された教師モデルがノイズ付きサンプルを1ステップ進め、オンラインの生徒モデルが軌道終点で指数移動平均(EMA)ターゲットから学習し、行動を考慮したフローマッチング項が行動予測を正則化します [5]。
本研究の適応:Fast-WAMの行動エキスパートのみを蒸留
私たちの実装はFast-WAMの推論グラフをそのまま維持します。生成された未来動画への依存を追加するのではなく、Fast-WAMが依然として反復生成を行う箇所、つまりActionDiTエキスパートにのみ一貫性目的関数を適用します。
この学習設定には3つの行動エキスパートが含まれます。
- 凍結された教師:公開Fast-WAMチェックポイントのActionDiTエキスパート。
- オンラインの生徒:教師から初期化された学習可能なコピー。
- EMAターゲット:オンライン生徒の凍結された移動平均。
VAE、動画エキスパート、固有受容エンコーダは凍結したままです。各サンプルについて、クリーンな最初のフレームをエンコードし、動画エキスパートに一度通して、Fast-WAMのネイティブ推論で使われるものと同じキー・バリューキャッシュを構築します。このキャッシュは教師、オンライン生徒、EMAターゲットで共有されるため、3つの行動予測すべてが同一の視覚・言語・固有受容条件を受け取ります。
一貫性目的関数
一貫性蒸留 [5, 7]を行動ストリームに特化して適用します。凍結された教師はノイズ付き行動をデノイジング軌道に沿って進め、オンライン生徒は、結果として得られる低ノイズ点で評価されたEMAターゲットに一致するよう学習します。
正規化された正解行動チャンク 、ガウスノイズ
、サンプリングされたノイズレベル
に対して、次のように構成します。
次に教師はフロー速度 を予測し、1回のオイラーステップで
まで進みます
行動ストリームでは、形式の一貫性出力を使います。
オンライン生徒の出力は、において、Huber損失の下で
におけるEMAターゲットに一致するよう学習します。FlashWAM [5]に従い、行動を考慮した項によって、オンライン速度をフローマッチングのターゲット
に近づけます。
これはモデルレベルでFlashWAMを再現するものではなく、行動側への適応です。動画を共同蒸留せず、Fast-WAM固有のシフト済み行動スケジューラを維持しています。
LIBEROでのオフライン学習
LIBERO-10、LIBERO-Goal、LIBERO-Spatial、LIBERO-Objectという4つの前処理済みLIBEROサブセット [8] のみを用いて学習しました。これらには277,713フレームと40個の固有の言語指示が含まれます。各サンプルには、2つのカメラビュー、行動チャンク、固有受容情報、事前計算済みテキスト埋め込みが含まれます。サンプリングは統合データセットの自然なフレーム分布に従います。
学習時のストライドは2ステップの軌道に合わせて設定しています。1ステップおよび2ステップの行動について完全なクローズドループ評価を報告し、元の10ステップFast-WAMポリシーを教師の基準とします。
条件を揃えたLIBERO評価結果
まず、本実験で妥当に行える比較の範囲を明確にします。以下のすべての行は、同一のFast-WAMアーキテクチャ、公開された初期化、オフラインLIBERO学習分布、ローカル評価手順を使用しています。各LIBEROスイートについて10タスク、各タスク50試行を実行し、合計2,000クローズドループエピソードとしました。公開Fast-WAMモデル [4]と同様、これらのバリアントはいずれも身体性事前学習を使用していません。
| バリアント | 行動ステップ | 蒸留の有無 | 成功率 | 成功エピソード | 10ステップとの差 | 行動NFE削減 |
|---|---|---|---|---|---|---|
| Fast-WAM基準 | 10 | いいえ | 97.60% | 1,952/2,000 | — | — |
| Fast-WAM、単純なステップ削減 | 2 | いいえ | 96.50% | 1,930/2,000 | -1.10 pp | 1/5 |
| 蒸留Fast-WAM(本研究) | 2 | はい | 96.80% | 1,936/2,000 | -0.80 pp | 1/5 |
| Fast-WAM、単純なステップ削減 | 1 | いいえ | 96.20% | 1,924/2,000 | -1.40 pp | 1/10 |
| 蒸留Fast-WAM(本研究) | 1 | はい | 96.55% | 1,931/2,000 | -1.05 pp | 1/10 |
スイート別に見ると、これらの合計値の内訳が分かります。Longは、原典のベンチマークに従いLIBERO-10を表します。
| バリアント | ステップ | Spatial | Object | Goal | Long | 平均 |
|---|---|---|---|---|---|---|
| Fast-WAM基準 | 10 | 98.2 | 100.0 | 97.0 | 95.2 | 97.6 |
| Fast-WAM、単純なステップ削減 | 2 | 97.6 | 99.2 | 95.8 | 93.4 | 96.5 |
| 蒸留Fast-WAM(本研究) | 2 | 96.8 | 99.6 | 96.6 | 94.2 | 96.8 |
| Fast-WAM、単純なステップ削減 | 1 | 98.0 | 99.4 | 95.6 | 91.8 | 96.2 |
| 蒸留Fast-WAM(本研究) | 1 | 97.0 | 98.8 | 97.0 | 93.4 | 96.55 |
最も重要な知見は、蒸留によって初めて少ステップFast-WAMが可能になったということではありません。公開モデルはすでに少ステップ推論に非常に適しています。単純な2ステップおよび1ステップ推論は、それぞれ96.5%と96.2%の成功率を維持します。蒸留は残るベンチマーク差をわずかに縮め、2ステップでは成功エピソードを6件(+0.30 pp)、1ステップでは7件(+0.35 pp)増やしました。評価シードを繰り返していないため、これらの小さな差を統計的に有意な改善とは解釈しません。
むしろ、この実験はFlash-WAMの一貫性目的関数を、ネイティブの推論グラフを変更せずにFast-WAMの行動ストリームへ移植できることを示します。また、ステップ蒸留の価値はWAMのアーキテクチャに依存することも示唆します。Fast-WAMでは、クリーンな観測による条件付けと分離された行動軌道により、積極的なステップ削減が比較的頑健になっている可能性があります。これは妥当なアーキテクチャ上の説明ですが、本ベンチマークで因果的に立証された主張ではありません。
1/5・1/10という数値はActionDiTの関数評価回数の削減のみを指し、エンドツーエンドの高速化と解釈すべきではありません。
前処理済みのGPU常駐観測とキャッシュ済みタスク埋め込みからCPU常駐の32行動チャンクまでを測定したところ、1ステップ蒸留Fast-WAMは、NVIDIA H100上でポリシー遅延を243 msから52 ms(4.63倍)に短縮しました。この計測にはVAE観測エンコード、固有受容条件付け、クリーンフレーム動画KVのプレフィル、ActionDiTのデノイジングとオイラー更新、出力転送を含みます。一方、テキストエンコード、モデル読み込み、シミュレーション、レンダリング、動画I/Oは除外しています。
同時期の研究:Faster-WAM
本記事の執筆中に、Faster-WAM [12] が2026年8月3日にarXivで公開されました。Faster-WAMは行動モジュール自体を再設計し、30層の動画バックボーンに軽量な単層行動ヘッドを接続することで、行動推論コストを削減します。同論文は、条件を揃えた比較においてエンドツーエンド遅延66.5 ms、Fast-WAMに対して3.2倍の高速化を報告しています [4]。
私たちの研究が対象とするのは別の計算軸です。公開Fast-WAMアーキテクチャを維持し、そのチェックポイントから開始して、学習後に行動デノイジングのステップ数を削減します。両者はアーキテクチャと評価環境が異なり、手法を組み合わせられるかも検証していないため、直接比較は行いません。
この実験が示すこと
Fast-WAMは、単純な1ステップおよび2ステップ推論でもLIBEROの高い成功率を維持します。行動側の一貫性蒸留は、残る差の一部をわずかに埋めるとともに、より重要な点として、動画由来の一貫性目的関数を行動のみの推論グラフへ移植できることを示します。本結果が裏付けるのは、ステップ圧縮下でもベンチマーク成功率が維持されるという点に限られます。行動軌道やポリシー挙動の同等性は評価していません。
公開ベンチマークの文脈
以下の数値はより広い分野の背景を示すものであり、条件を揃えた本実験とのリーダーボード形式の比較ではありません。各手法はアーキテクチャ、身体性事前学習、データ、評価手順が異なるため、この表を蒸留による改善の帰属や、上記5つのローカルFast-WAM設定の順位付けに使うべきではありません。
| 手法 | 身体性事前学習 | Spatial | Object | Goal | Long | 平均 |
|---|---|---|---|---|---|---|
| OpenVLA [9] | ✓ | 84.7 | 88.4 | 79.2 | 53.7 | 76.5 |
| ✓ | 96.8 | 98.8 | 95.8 | 85.2 | 94.1 | |
| ✓ | 98.8 | 98.2 | 98.0 | 92.4 | 96.9 | |
| Motus [2] | ✓ | 96.8 | 99.8 | 96.6 | 97.6 | 97.7 |
| LingBot-VA [1] | ✓ | 98.5 | 99.6 | 97.2 | 98.5 | 98.5 |
| 蒸留LingBot-VA(Flash-WAM)[5]、2ステップ | ✓ | 97.0 | 92.8 | 96.4 | 98.0 | 95.7 |
| 蒸留LingBot-VA(Flash-WAM)[5]、1ステップ | ✓ | 96.0 | 92.6 | 96.0 | 95.8 | 95.1 |
参考文献
[1] Causal World Modeling for Robot Control. arXiv:2601.21998
[2] Motus: A Unified Latent Action World Model. arXiv:2512.13030
[3] World Action Models are Zero-shot Policies. arXiv:2602.15922
[4] Fast-WAM: Do World Action Models Need Test-time Future Imagination? arXiv:2603.16666
[5] Flash-WAM: Modality-Aware Distillation for World Action Models. arXiv:2606.05254
[6] Wan: Open and Advanced Large-Scale Video Generative Models. arXiv:2503.20314
[7] Consistency Models. arXiv:2303.01469
[8] LIBERO: Benchmarking Knowledge Transfer in Lifelong Robot Learning. arXiv:2306.03310
[9] OpenVLA: An Open-Source Vision-Language-Action Model. arXiv:2406.09246
[10] : A Vision-Language-Action Flow Model for General Robot Control. arXiv:2410.24164
[11] : A Vision-Language-Action Model with Open-World Generalization. arXiv:2504.16054
[12] Faster-WAM: Do World Action Models Need Deep Action Modules? arXiv:2608.02365
