(Japanese version follows English one/英語版の後に日本語版が続きます。)
Contributor
Core contributor: Chen Zhu
Project Lead: Shiqi Yang
Creative Vision Team, Multimodal AI Department
Introduction
Video generation is cool and has reached a relatively mature state, but when it comes to real-world applications, we believe that conversational characters, where users can interact with the generated character through either text or speech, offer a clearer path toward interactive applications such as virtual assistants, live entertainment, customer support, and embodied interfaces. As our first attempt in this direction, we chose to start with streaming speech-driven video generation, where the model takes streaming speech as input and generates the corresponding streaming video/character response. Interaction can be achieved with external models: for example, we can use some Omni MLLM to process the user input (either speech or text) and output a reply in speech form, which is then used as the condition to guide video generation. In this blog, we share our recent progress on speech-driven video generation, with a particular focus on streaming talking-character scenarios, and describe how we built an initial end-to-end prototype capable of generating a streaming character response from conversational speech.
Overview of the Workflow
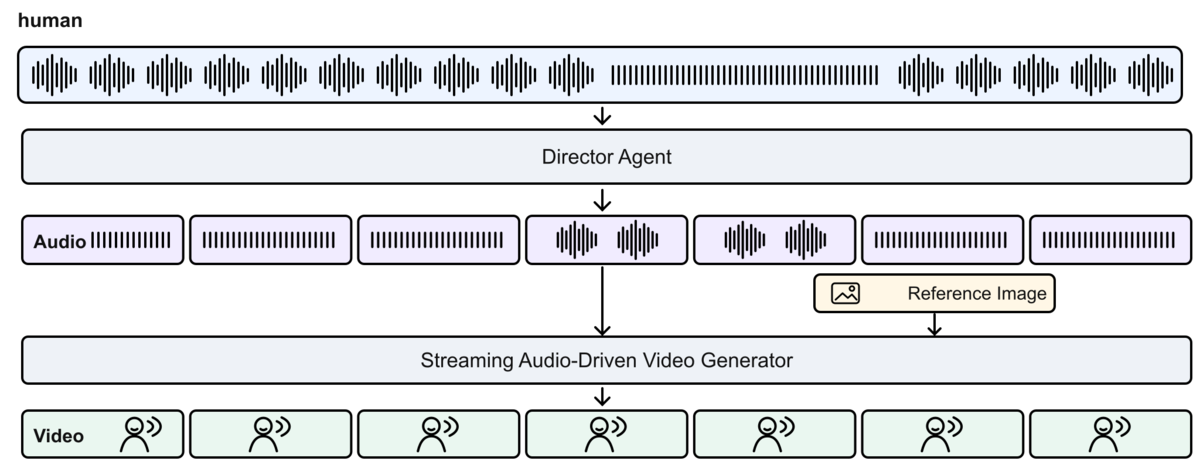
The workflow starts with the user's speech and an uploaded character reference image. A director agent (which could be a speech/omni MLLM such as Moshi [1], MiniCPM-o 4.5 [2], or Ming-flash-omni [3], or a combination of ASR + LLM + TTS; in our deployment we simply pick one omni MLLM) processes the user's speech and outputs a reply in speech form. Note that the speech output from the director is also expected to be produced in a streaming manner, thus reducing latency. The streaming reply speech chunks, together with the reference image, are sent to a streaming speech-driven video generation model to generate the talking character. A text prompt is also provided to the generation model, which the user can specify to control certain visual elements. The video latents are then decoded by the video VAE decoder in a streaming manner.
Key Challenges
-
Long-term consistency maintenance
-
Low-latency real-time generation
Model Training: Autoregressive Speech-Driven Video Generation
Base Audio-Video Generation Model
Quite a few open-source joint audio-video generation models have been released recently — LTX2/2.3 [4], Davinci-Magihuman [5], and MOVA [6], to name a few — as well as some audio-driven video generation models such as LongCat-Video-Avatar [7]. We chose to directly use LTX 2.3 (without the upsampler) as the base model, and post-train it to obtain an autoregressive speech-driven video generation model.
Autoregressive Post-training
Most existing streaming/long-video fine-tuning methods for video and audio-video generation follow Self-Forcing [8] or other similar pathways, where the model is trained to roll out predictions conditioned on its own historical predictions. We adopt the Self-Forcing framework with several improvements. The training process is divided into two stages.
Stage 1: ODE Initialization
We convert the original bidirectional base model into a causal model with a small number of inference steps (4 or 6). This aims to provide a good starting point for autoregressive training. We perform this stage using a relatively small subset of the VividHead dataset, with text, a reference image, and speech as conditioning signals. At this point, the model is initialized from the LTX 2.3 Distilled model. We chose not to use the LTX 2.3 base model (non-distilled), since we found it cannot guarantee a good starting point for the later DMD distillation stage. This is somewhat similar to the findings in LiveTalk [9] (where full-timestep sampling is used) and OmniForcing [10] (where bidirectional DMD is conducted before ODE initialization). As mentioned above, we assume that during inference the director agent sends streaming audio/speech chunks to the video generation model. Therefore, here and hereafter, for audio branch we apply a chunk-local attention mask to the audio tokens, allowing each audio token to attend only to tokens from the same incoming audio chunk, preventing the model from relying on future audio chunks unavailable during streaming. We find this helps stabilize training.
Stage 2: DMD Distillation
After ODE initialization, the model is further trained to perform self-rollout based on its own predictions, supervised by a real scorer and a fake scorer. The real scorer estimates the target distribution represented by real data, while the fake scorer tracks the distribution produced by the current student model. In the original Self-Forcing framework, the real and fake scorers are usually initialized from the base model; here, however, we choose to initialize the real scorer with the LTX 2.3 base (non-distilled) model. Additionally, we initialize the fake scorer with the ODE-initialized model. We find that this setting avoids the frame-flipping issue, which occurs under the original Self-Forcing setting. We posit that this is because the student model after ODE initialization is already a speech-conditioned model. Initializing the fake scorer from the original non-speech-conditioned LTX model creates a distribution mismatch with the speech-conditioned student rollout. For the real scorer, we do not apply the chunk-local attention mask.
Inference
During inference, we retain the tokens from the reference image and the first generated video chunk as persistent attention sinks, providing stable identity anchors throughout the autoregressive rollout.
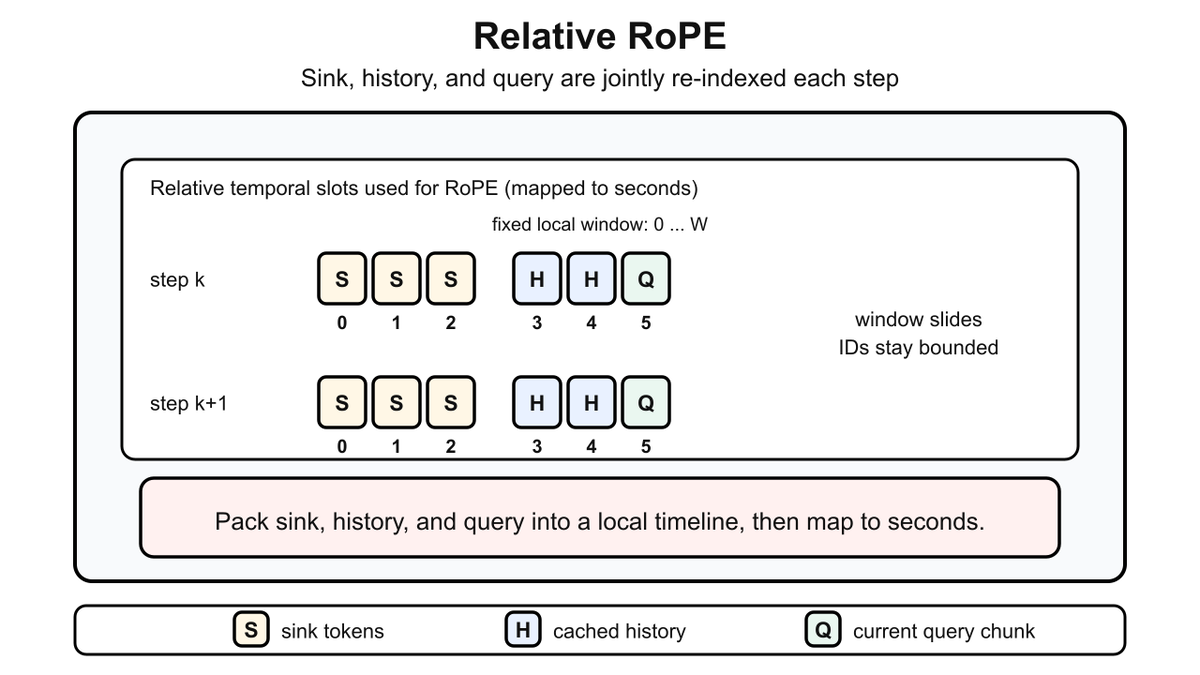
LTX applies RoPE to continuous timestamps in seconds. Since rotary attention depends only on pairwise temporal differences, shifting the whole timeline by a constant leaves attention scores unchanged. If persistent sinks stay fixed at their initial times, however, their distance to later queries grows without bound as streaming continues. A further subtlety is that the causal VAE gives the first latent frame a different temporal extent than later frames, so the map from latent index to seconds is not translation-invariant near the origin: early-clip timing in second space is not just a shifted copy of later, uniformly spaced frames. We therefore apply relative RoPE for self-attention. At each step, we pack the persistent sinks, retained history, and current chunk into a bounded local latent-frame schedule, then recompute their coordinates in seconds. This keeps sink-query offsets within the attention window while preserving the local timing induced by the causal VAE. For audio-video cross-attention we keep the shared global timeline, so audiovisual alignment is preserved.
System Design
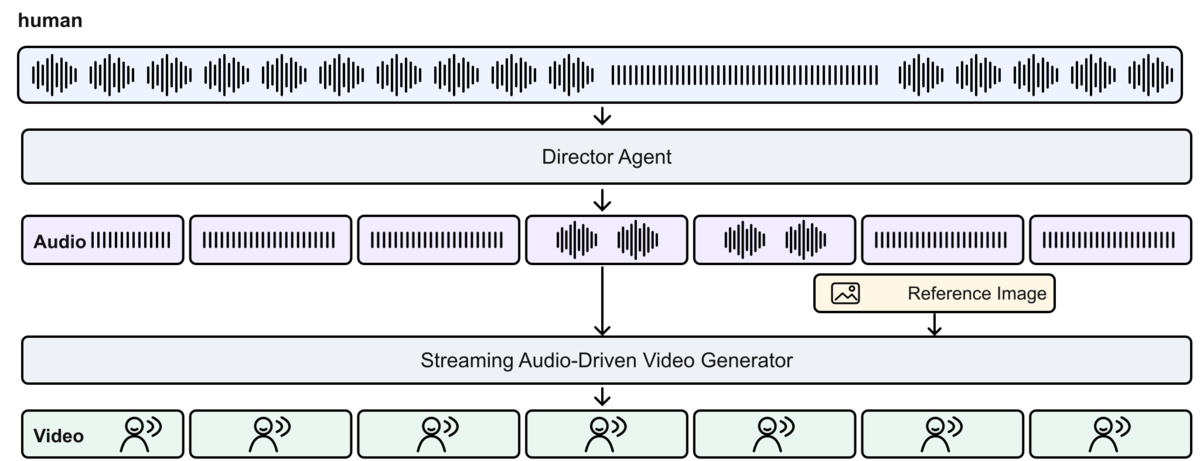
As illustrated above, our system consists of a director agent and a streaming audio-driven video generation model. The director agent receives user speech and generates the character's reply as streaming speech chunks. These chunks are immediately passed to the video generation model, together with the character's reference image. The generated video latents are then decoded and played back in a streaming manner. Since every component operates incrementally, the character can begin responding before the director agent has finished generating the complete reply. This separation also allows the director agent to handle dialogue and reasoning independently of the video model, making it possible to replace either component without retraining the other.
To support smooth and deadlock-free multi-turn conversations, we maintain an explicit session state across the director agent, video generator, and video player. The character continuously alternates between listening and speaking states: while waiting for reply audio, it generates subtle listening motion; when the first speech chunk of a new reply arrives, we select a recent listening frame as the visual anchor for the speaking rollout. Audio chunks are then consumed in order as they arrive, while playback-aware flow control prevents the generator from running too far ahead of the player. Once the reply ends, the session returns to the listening state and becomes ready for the next turn. Together, these mechanisms avoid blocked transitions and provide a continuous visual experience across multiple conversational turns.
Streaming Deployment and Performance
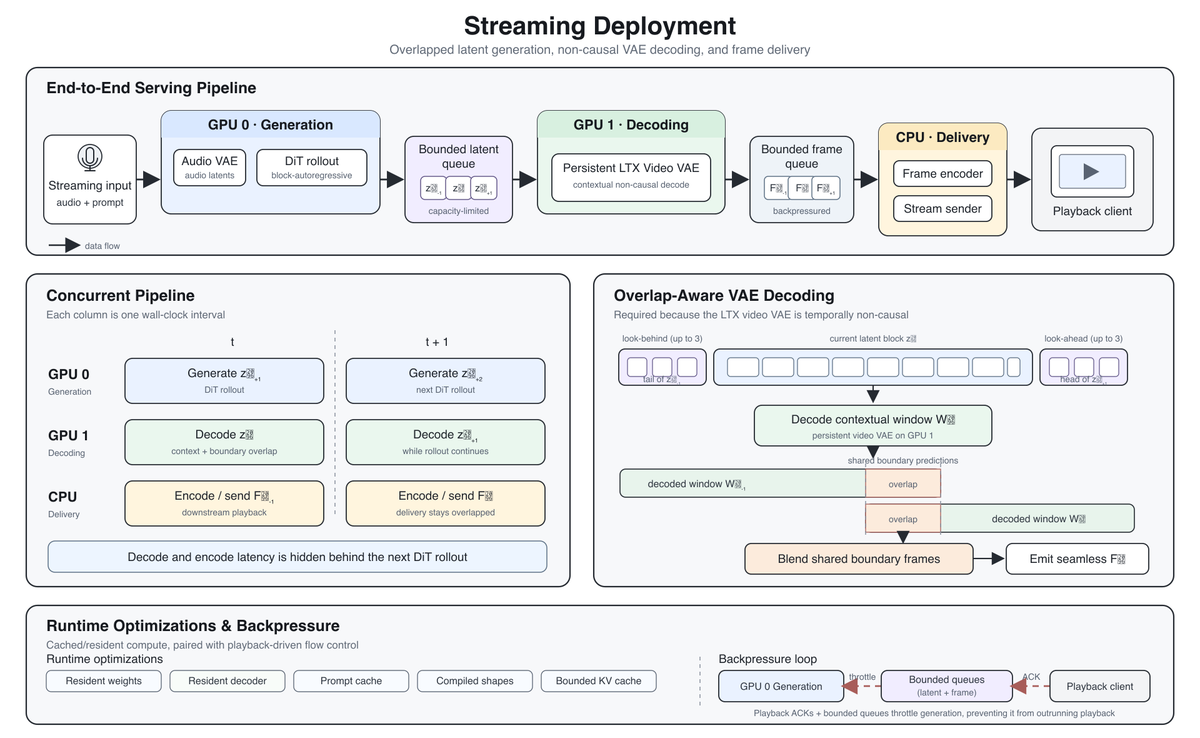
Deploying the model as an end-to-end streaming service requires a serving architecture that extends beyond block-autoregressive generation. We decouple latent generation from video decoding and execute them as concurrent pipeline stages. The audio VAE and DiT generator run on one GPU, while a persistent video VAE decoder runs on a second GPU. Generated latent blocks are transferred through a bounded queue and decoded in parallel with subsequent DiT rollouts. Meanwhile, a dedicated CPU worker encodes the decoded frames and delivers them to a downstream playback client. By overlapping latent generation, VAE decoding, and frame delivery, this architecture minimizes pipeline bubbles and hides most of the decoding and encoding latency behind DiT inference, thereby improving hardware utilization and end-to-end streaming throughput.
Streaming VAE decoding requires special handling because the LTX video VAE is not temporally causal. Decoding every latent block independently introduces visible discontinuities at block boundaries. We therefore decode each block with a small temporal context: up to three latent frames from the previous block and three latent frames from the next block. Frames predicted by overlapping decoding windows are blended at their shared boundary before being sent to the player. We apply several additional runtime optimizations. The model weights and video decoder remain resident in GPU memory, prompt conditioning is cached across conversation turns, and the shape-stable parts of the transformer are compiled. During generation, a bounded persistent KV cache avoids recomputing previous video blocks. Playback acknowledgements and bounded queues provide backpressure, preventing the generation server from running arbitrarily far ahead of the browser during a long conversation.
Our current prototype generates 512 × 512 video at 25 FPS. At steady state, the pipeline produces approximately 1.28 seconds of video in 0.8-0.9 seconds, enabling faster-than-real-time generation. Streaming VAE decoding takes approximately 0.5-0.6 seconds per block, but most of this latency is hidden by overlapping decoding with the subsequent DiT rollout.
Demo
(Demos with virtual character but real person character also supported)
The demo below shows the complete system in action. The user speaks naturally to the character, while the director agent generates a streaming speech reply and the video model renders the corresponding facial motion. Across multiple turns, the character moves continuously between listening and speaking, without returning to the original reference image after each reply. The system preserves the character's appearance while maintaining synchronized speech and facial motion throughout the conversation.
日本語版
ストリーミング音声駆動動画生成によるリアルタイム対話型キャラクターの実現
執筆メンバー
主要貢献者:Chen Zhu
プロジェクトリード:Shiqi Yang
マルチモーダルAI部 クリエイティブ・ビジョンチーム
はじめに
近年、動画生成技術は急速に進歩し、実用化のフェーズに入りつつあります。その中でも私たちが特に可能性を感じているのが、ユーザーがテキストや音声を通じてキャラクターとやり取りできる「対話型キャラクター」です。対話型キャラクターは、バーチャルアシスタント、ライブエンターテインメント、カスタマーサポート、身体性を備えたインターフェースなど、さまざまなインタラクティブサービスへの応用が期待できます。
この方向性への最初の取り組みとして、私たちはストリーミング音声駆動動画生成に着手しました。これは、ストリーミングで入力される音声に合わせて、キャラクターの動画をリアルタイムに近い形で生成する技術です。対話部分は、外部のモデルと組み合わせることで実現できます。例えば、Omni MLLMを使ってユーザーの音声またはテキストを処理し、応答音声を生成します。その音声を条件として動画生成モデルに入力することで、キャラクターが話している映像を生成できます。
本記事では、音声駆動動画生成に関する私たちの最近の取り組みを紹介します。特に、ストリーミングで動作する対話型キャラクターに焦点を当て、会話音声からキャラクターの応答動画を生成するエンドツーエンドのプロトタイプを、どのように構築したかについて説明します。
システム全体の流れ
ワークフローは、ユーザーの音声と、アップロードされたキャラクターの参照画像から始まります。ディレクターエージェントには、Moshi [1]、MiniCPM-o 4.5 [2]、Ming-Flash-Omni [3]などの音声対応Omni MLLMを利用できます。また、ASR、LLM、TTSを組み合わせた構成も可能です。今回のデプロイでは、単一のOmni MLLMを採用しています。
ディレクターエージェントはユーザーの音声を処理し、応答音声をストリーミングで生成します。これにより、応答全体の生成を待つことなく、動画生成を開始できます。生成された応答音声チャンクは、参照画像とともにストリーミング音声駆動動画生成モデルへ送られ、キャラクターの発話動画が順次生成されます。モデルにはテキストプロンプトも入力でき、ユーザーは映像内の特定の視覚要素をコントロールできます。生成された動画の潜在表現は、動画VAEデコーダーによって順次デコードされます。
主な課題
-
長期的な一貫性の維持
-
低レイテンシでのリアルタイム生成
モデル学習:自己回帰型の音声駆動動画生成
ベースとなる音声・動画生成モデル
近年、LTX-2/2.3 [4]、DaVinci Magihuman [5]、MOVA [6]など、音声と動画を同時に生成するオープンソースモデルが相次いで公開されています。また、LongCat-Video-Avatar [7]のような音声駆動動画生成モデルも登場しています。私たちは、アップサンプラーを使用しないLTX 2.3をベースモデルとして採用し、追加学習によって自己回帰型の音声駆動動画生成モデルを構築しました。
自己回帰生成に向けた追加学習
既存のストリーミング動画生成や長時間動画生成向けのファインチューニング手法の多くは、Self-Forcing [8]、またはそれに近い学習方法を採用しています。Self-Forcingでは、モデル自身が過去に生成した予測結果を条件として、後続の予測をロールアウトできるように学習します。私たちもSelf-Forcingのフレームワークを採用していますが、いくつかの改良を加えています。学習プロセスは、以下の2つのステージに分かれています。
ステージ 1:ODE 初期化
最初のステージでは、元の双方向モデルを、4ステップまたは6ステップという少ないステップ数で推論できる因果モデルに変換します。このステージの目的は、後段の自己回帰学習を安定して始められる初期モデルを作ることです。学習には、VividHeadデータセットの比較的小規模なサブセットを使用しました。条件として、テキスト、キャラクターの参照画像、音声を入力します。
モデルの初期値には、LTX 2.3 Distilledモデルを使用しています。LTX 2.3の非蒸留ベースモデルについても検証しましたが、後段のDMD蒸留を安定して始めるための初期モデルとしては十分ではありませんでした。この点は、全タイムステップでサンプリングを行うLiveTalk [9]や、ODE初期化の前に双方向DMDを行うOmniForcing [10]の設計とも、ある程度共通しています。
推論時には、ディレクターエージェントから動画生成モデルへ、音声がチャンク単位で順次送られます。そのため、学習時にも音声トークンに対してチャンク内アテンションマスクを適用しています。このマスクを使うと、各音声トークンは、同じ音声チャンク内のトークンだけを参照します。まだ入力されていない未来の音声チャンクを見ることはできません。これにより、学習時にだけ利用できる未来の音声情報へモデルが依存してしまうことを防げます。実験では、この処理によって学習がより安定することを確認しました。
ステージ 2:DMD 蒸留
ODE初期化の後は、モデル自身が生成した結果を使って、連続的にロールアウトできるように追加学習を行います。この学習では、real scorerとfake scorerという2つのスコアモデルを使用します。real scorerは、実データが持つターゲット分布を推定します。一方、fake scorerは、現在の生徒モデルが生成しているデータの分布を追跡します。
元のSelf-Forcingでは、real scorerとfake scorerの両方を、通常は同じベースモデルから初期化します。今回の構成では、real scorerをLTX 2.3の非蒸留ベースモデルから初期化します。一方、fake scorerには、ステージ1でODE初期化を行ったモデルを使用します。この構成にすることで、元のSelf-Forcingの設定で発生していた、映像フレームが反転する問題を抑えられることが分かりました。原因の一つとして、ODE初期化後の生徒モデルが、すでに音声を条件として生成するモデルになっていることが考えられます。これに対して、fake scorerを音声条件を持たない元のLTXモデルから初期化すると、音声条件付きの生徒モデルが生成する分布との間にずれが生じます。なお、real scorerにはチャンク内アテンションマスクを適用していません。
推論
推論時には、参照画像のトークンと、最初に生成した動画チャンクのトークンを、継続的に保持するattention sinkとして利用します。これらのトークンを生成の途中で削除せずに残すことで、長時間生成を続けた場合でも、キャラクターの顔や見た目を安定させやすくなります。
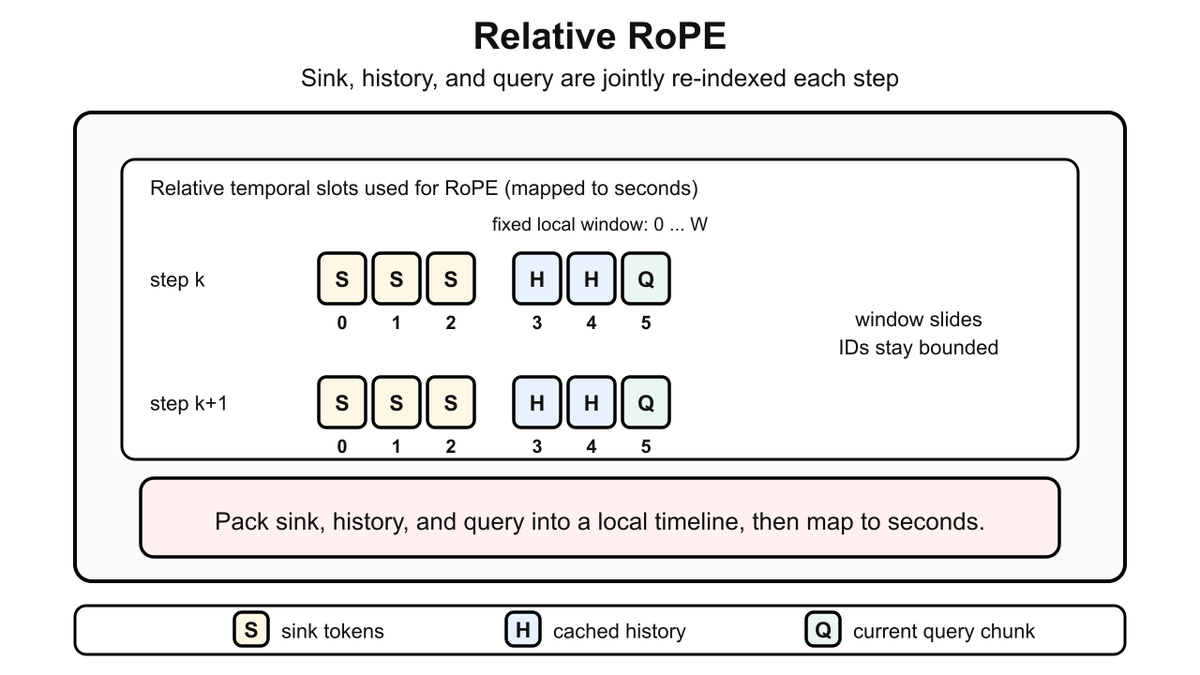
LTXでは、秒単位の連続したタイムスタンプに対してRoPEを適用しています。ロータリーアテンションは、トークン間の相対的な時間差によって決まります。そのため、タイムライン全体を同じ時間だけずらしても、アテンションスコア自体は変化しません。一方で、attention sinkを最初のタイムスタンプに固定したまま生成を続けると、sinkと新しく生成するチャンクとの時間差が徐々に大きくなっていきます。また、因果VAEでは、最初の潜在フレームだけが、それ以降の潜在フレームとは異なる時間幅を表します。そのため、動画の冒頭部分と後半部分では、潜在フレームのインデックスから秒単位の時刻へ変換する関係が完全には一致しません。単純にタイムスタンプ全体をずらすだけでは、冒頭部分の時間構造を再現できないという問題があります。そこで、セルフアテンションには相対RoPEを使用しています。各生成ステップで、attention sink、保持している履歴、現在生成するチャンクを、一定範囲内のローカルな潜在フレーム座標に並べ直します。その後、因果VAEの時間構造に合わせて、秒単位のタイムスタンプを再計算します。これにより、attention sinkと現在のチャンクとの時間差が大きくなりすぎることを防ぎながら、因果VAEが持つ局所的な時間構造を維持できます。一方、音声と動画のクロスアテンションには、共通のグローバルタイムラインを使用します。これにより、音声と映像の時間的な同期を保っています。
システム設計
下記の図に示すように、本システムは、ディレクターエージェントとストリーミング音声駆動動画生成モデルで構成されています。ディレクターエージェントはユーザーの音声を受け取り、キャラクターの応答音声をチャンク単位で順次生成します。生成された音声チャンクは、キャラクターの参照画像とともに、すぐに動画生成モデルへ渡されます。動画生成モデルが出力した潜在表現は、順次デコードされ、そのまま再生されます。すべてのコンポーネントがストリーミングで動作するため、ディレクターエージェントが応答全体を生成し終わる前に、キャラクターは話し始めることができます。また、対話処理を担当するディレクターエージェントと、映像生成を担当する動画モデルを分離しています。
これにより、対話や推論のロジックと動画生成を独立して開発できます。どちらか一方のモデルを変更する場合でも、もう一方のモデルを再学習する必要はありません。複数ターンの対話を途切れずに進めるため、ディレクターエージェント、動画生成モデル、動画プレイヤーの間で、セッションの状態を明示的に管理しています。キャラクターは、「聞いている状態」と「話している状態」を交互に切り替えます。応答音声を待っている間は、完全に静止するのではなく、相手の話を聞いているような小さな待機モーションを生成します。新しい応答の最初の音声チャンクが届くと、直前の待機モーションから適切なフレームを選び、そのフレームを起点として発話中の動画生成を開始します。音声チャンクは、到着した順番に処理されます。また、再生状況に応じたフロー制御を行い、動画生成がプレイヤーよりも先に進みすぎないようにしています。応答が終了すると、キャラクターは再び聞いている状態に戻り、次のユーザー入力を受け付けます。これらの仕組みによって、状態の切り替えで処理が止まったり、デッドロックが発生したりすることを防ぎ、複数ターンにわたって自然に動き続けるキャラクターを実現しています。
 ストリーミング環境へのデプロイと性能
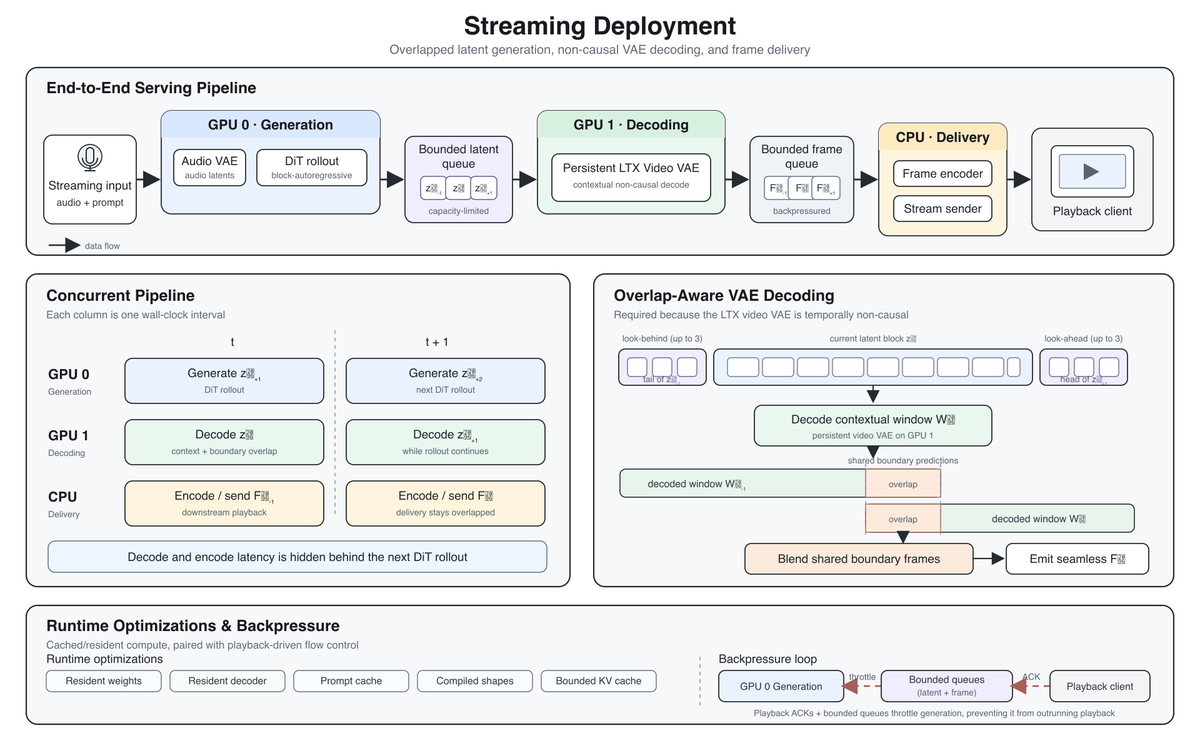
モデルをエンドツーエンドのストリーミングサービスとして動かすには、動画をブロック単位で自己回帰生成するだけでなく、それぞれの処理を効率よく並列実行するためのサービング構成が必要です。本システムでは、動画の潜在表現を生成する処理と、潜在表現を動画フレームへデコードする処理を分離し、パイプラインとして並列に実行しています。音声VAEとDiT生成モデルは1枚目のGPU上で動かします。動画VAEデコーダーは2枚目のGPU上に常駐させます。生成された潜在ブロックは、サイズに上限を設けたキューを通じて動画VAEデコーダーへ送られます。動画VAEが現在のブロックをデコードしている間に、DiTは次のブロックを生成します。さらに、専用のCPUワーカーがデコード済みの動画フレームをエンコードし、再生クライアントへ送信します。潜在表現の生成、VAEデコード、フレーム送信を重ねて実行することで、各処理の間に発生する待ち時間を減らしています。また、動画のデコードやエンコードにかかる時間の大部分をDiTの推論中に処理できるため、GPUの利用効率と、システム全体のストリーミング性能を向上させることができます。
LTXの動画VAEは、時間方向に因果的なモデルではありません。そのため、ストリーミングでデコードするには追加の工夫が必要です。各潜在ブロックを完全に独立してデコードすると、ブロックの境界で映像が不自然に切り替わったり、ちらつきが発生したりします。そこで、各ブロックをデコードする際に、前後の潜在フレームをコンテキストとして追加しています。具体的には、前のブロックから最大3フレーム、次のブロックから最大3フレームを含めてデコードします。複数のデコード範囲で重複して生成されたフレームについては、境界部分をブレンドしてからプレイヤーへ送ります。これにより、ブロック間の不連続を目立ちにくくしています。このほかにも、実行時にはいくつかの高速化を行っています。モデルの重みと動画VAEデコーダーはGPUメモリ上に常駐させます。プロンプトの条件情報は、複数の対話ターンをまたいでキャッシュします。また、Transformerのうち、入力形状が固定される部分についてはコンパイルを行っています。生成中は、サイズに上限を設けた永続KVキャッシュを使用します。これにより、過去の動画ブロックを毎回計算し直す必要がなくなります。さらに、ブラウザから送られる再生確認のACKと上限付きキューを使ってバックプレッシャーをかけています。長時間の対話中でも、生成サーバーがブラウザの再生より先に進みすぎないように制御します。
現在のプロトタイプは、512 × 512ピクセル、25 FPSの動画生成に対応しています。定常状態では、約1.28秒分の動画を0.8~0.9秒で生成できます。そのため、生成速度はリアルタイムを上回っています。ストリーミングVAEのデコードには、1ブロックあたり約0.5~0.6秒かかります。ただし、次のDiT生成と並列に処理することで、デコードにかかる待ち時間の大部分を表面上は見えないようにしています。
デモ
(バーチャルキャラクターによるデモに加え、実在の人物にも対応しています。)
以下のデモでは、システム全体の動作を確認できます。ユーザーがキャラクターに自然に話しかけると、ディレクターエージェントが応答音声をストリーミングで生成します。同時に、動画生成モデルが音声に合わせたキャラクターの表情や口の動きを生成します。複数ターンの対話でも、キャラクターは応答が終わるたびに元の参照画像へ戻ることなく、聞いている状態と話している状態の間を連続的に移動します。対話中もキャラクターの見た目を維持しながら、音声と表情、口の動きの同期を保つことができます。
Reference / 参考文献
[1] Moshi: a speech-text foundation model for real-time dialogue. arXiv:2410.00037
[2] MiniCPM-o 4.5: Towards Real-Time Full-Duplex Omni-Modal Interaction. arXiv:2604.27393
[3] Ming-Flash-Omni: A Sparse, Unified Architecture for Multimodal Perception and Generation. arXiv:2510.24821
[4] LTX-2: Efficient Joint Audio-Visual Foundation Model. arXiv:2601.03233
[5] DaVinci Magihuman: Speed by Simplicity — A Single-Stream Architecture for Fast Audio-Video Generative Foundation Model. arXiv:2603.21986
[6] MOVA: Towards Scalable and Synchronized Video-Audio Generation. arXiv:2602.08794
[7] LongCat-Video-Avatar Technical Report. arXiv:2605.26486
[8] Self Forcing: Bridging the Train-Test Gap in Autoregressive Video Diffusion. arXiv:2506.08009
[9] LiveTalk: Real-Time Multimodal Interactive Video Diffusion via Improved On-Policy Distillation. arXiv:2512.23576
[10] OmniForcing: Unleashing Real-time Joint Audio-Visual Generation. arXiv:2603.11647
